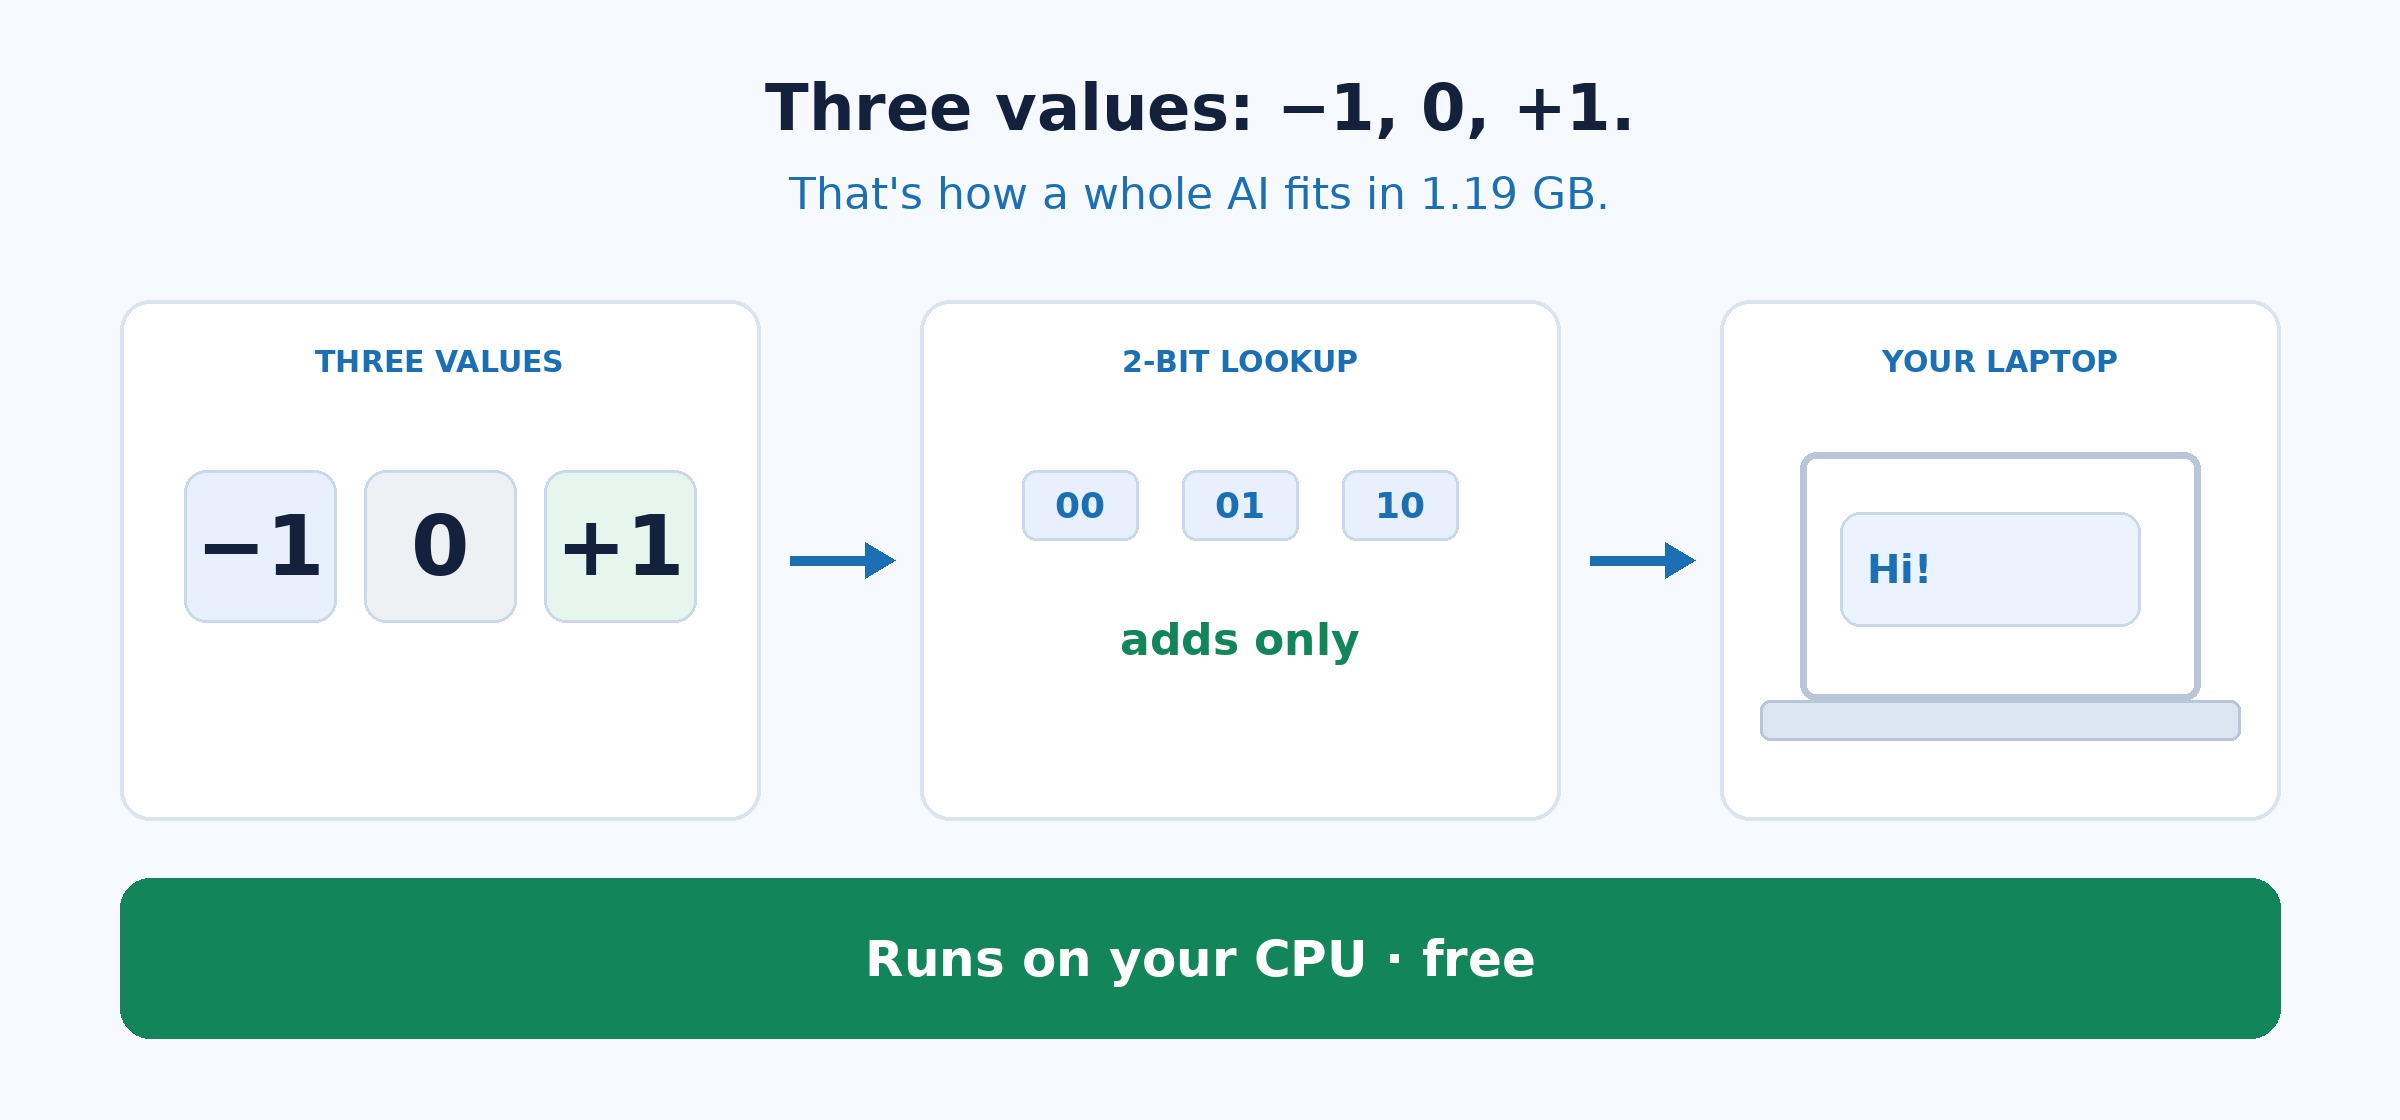
Download one 1.19 GB file, open it on an ordinary laptop, and it answers you — no graphics card, no account, nothing to rent.
Microsoft’s BitNet stores every brain-weight as one of three values: −1, 0, +1. A tiny lookup turns those values into words using only addition. That’s why the file is smaller than most phone games.
What you actually get
 BitNet — Microsoft’s 1-bit AI engine, MIT-licensed, ~42k stars.
 The model you can download today: 2.4B parameters, 1.19 GB — about 1.5 GB of RAM while it runs.
 Measured: 1.37–5.07× faster on Apple CPUs, 2.37–6.17× on Intel, with 55–82% less energy than ordinary 16-bit AI.
 The win is the map, not the model: three values plus a lookup beat stacking more graphics cards.
See it before you install
 Official live demo — type a question, get an answer.
 2.31 MB toy — 11 million parameters, and you can watch its brain as −1 / 0 / +1 signs.
 0xBitNet chat — the full 2B model runs inside your browser; nothing leaves your machine.
 Speed scoreboard — real tokens-per-second numbers on a cheap machine.
Put it on your laptop
BitRun — one install line, prebuilt files, a speed dashboard, and a 79 MB starter model.
 Official build — clone the repo, then:
git clone --recursive https://github.com/microsoft/BitNet.git
cd BitNet
conda create -n bitnet-cpp python=3.10 && conda activate bitnet-cpp
pip install -r requirements.txt
huggingface-cli download microsoft/BitNet-b1.58-2B-4T-gguf --local-dir models/BitNet-b1.58-2B-4T
python setup_env.py -md models/BitNet-b1.58-2B-4T -q i2_s
 Fast mode needs AVX2 on x86, or NEON on ARM.
Push it further
 FairyFuse — same three values, a kernel that only adds and subtracts: 29.6× faster kernel, 32.4 tokens/s on one Intel server chip. Authors’ measurements, early paper.
 Litespark — one
pip install, then load a real 1-bit model; up to 18× throughput on Apple silicon. Early paper.
 T-MAC — the lookup trick now inside bitnet.cpp: 3.4× on an M2 Ultra, 5.8× on a Raspberry Pi 5. Peer-reviewed.
 DeepSeek-R1 671B — a real 671-billion-parameter model packed into 131 GB; works on ~20 GB of RAM, slowly.
 LittleBit — research pack putting Llama2-13B under 0.9 GB. Early research, quality drops.
Bigger than your RAM
 SSD offload — a 25 GB model on a 16 GB laptop with two extra launch flags.
PocketLLM — stream a 30B model off a USB stick in 6 GB of RAM. New project.
 solid.cpp — a one-line patch that lets a 93 GB model page from disk on a 42 GB machine. New project.
 DistAi — pool three old phones over USB into one 14B machine; keep it on a private network.
ik_llama.cpp — one -rtr 1 flag gave up to 7× faster prompt reading on the same CPU.
No machine? Use free compute
 Cloudflare Workers AI — 10,000 free units a day, roughly 49,000 output tokens on a 70B model, no card.
GitHub Models — your GitHub login is the key; 40+ models from an Action.
 Hugging Face thin Space — host a big-model demo that bills the visitor instead of your free quota.
Kaggle — 30 h/week of free 32 GB graphics cards · GitHub Actions — free CPUs you can fan out.
Read once before you start
 The “100-billion” line going around the web is a benchmark setting in the paper, not a download. The model you can actually get is 2.4B / 1.19 GB; that benchmark ran 6.58 tokens/s on a Mac Studio, 1.70 on an Intel laptop (source).
 The official source has a one-line activation fix in PR #642 — applying it restores the intended answer quality (perplexity 17.1 instead of 99.8). Windows builders are tracking PR #644.
For loading the model yourself, use bitnet.cpp or the browser demos — app support is still arriving (request).
FairyFuse and Litespark are early papers — the numbers are the authors’ own measurements.
Free compute tiers are for your own experiments; keep them personal.
 !