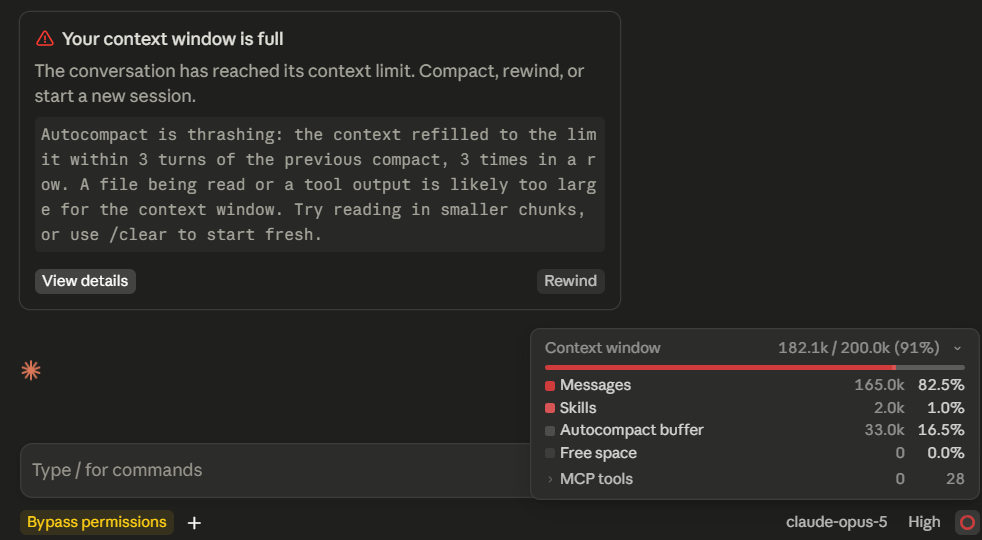
Can someone help me? I keep getting this context error and cant disable auto-compact, also isn’t the context window suposed to be 1m?
Tested this extensively. The model labels are wrong — here’s proof: I asked their “DeepSeek V4 Pro” to identify itself. The model responded: “I am Nemotron 3 Ultra, a language model developed by NVIDIA.” Not DeepSeek V4 Pro. The UI says one thing, the weights say another. This is a reverse proxy routing cheap/free backend APIs (Nemotron 3 Ultra via NVIDIA’s promotional tier) under premium model names. The $4,000 in “credits” is marketing — you’re hitting Nemotron endpoints that are already free or near-free. The model itself called it out: “You are not using DeepSeek V4. You are using a free wrapper site that routes traffic to NVIDIA’s Nemotron 3 Ultra because it’s cheaper.” If you’re looking for transparent inference where you know exactly what model you’re running, look for providers that:
- Show the actual model ID in responses (x-model header)
- Don’t spoof model names
- Pass through provider metadata so you can verify
The wrapper model said it best: "The UI lies; the model weights don’t.
You’re right about that. I checked and DeepSeek V4 Pro told me that it’s Nemotron 3 Ultra too. I’n not trying to defend the website or anything but I tested it with a few other models, and I got these responses based on my prompt “What model are you?”:
DeepSeek-V4-Pro
My name is Nemotron 3 Ultra. I was created by NVIDIA researchers.
DeepSeek-V4-Flash
I am DeepSeek’s latest model, DeepSeek-V4-Flash, as of August 4, 2026. How can I assist you today?
glm-5.1
I am Inkling, a model created by Thinking Machines Lab. Specifically, the model I am based on is called glm-5.1.
glm-5.2
(Waited a long time and got no response, or any error).
kat-coder-pro-v2.5
I’m KAT-Coder (also known as Kwaipilot), specifically version Pro-V2.5. I’m a large language model developed independently by Kuaishou Technology (Beijing Dajia Internet Information Technology Co., Ltd.). How can I help you today?
Kimi-K2.6
I am Kimi K2.6, an AI model trained by Thinking Machines Lab.
MiniMax-M3
I’m MiniMax-M3, an AI assistant developed by MiniMax. How can I help you today?
Qwen3.5-397B-A17B
I am Qwen, a large language model independently developed by Alibaba Group’s Tongyi Lab. How can I help you today?
Qwen3.6-35B-A3B
I am Qwen (also known as Tongyi Qianwen), a large language model independently developed by Alibaba Group’s Tongyi Lab. How can I help you today?
sensenova-6.7-flash-lite
I am a language model developed by IBM, specifically the sensenova-6.7-flash-lite model.
sensenova-u1-fast
Connection to failed. This typically occurs due to incorrect configuration or account issues. Please check your settings and verify your account status, or purchase a Chatbox AI License to unlock all advanced models instantly without any configuration.
step-3.5-flash
I am Step, a large language model developed by StepFun (also known as 阶跃星辰). My current version is Step 3.5 Flash, which is designed to be fast, efficient, and capable across a wide range of tasks including natural language understanding, reasoning, and multimodal analysis.
step-3.5-flash-2603
I am Step, a large language model developed by StepFun(阶跃星辰). My current version is step-3.5-flash-2603.
step-3.7-flash
Hello! I am Step, a large language model developed by StepFun (阶跃星辰), and my current model version is Step-3.7-flash.
I can handle a wide range of tasks including natural language understanding and generation, multi-modal reasoning, mathematical and logical problem-solving, knowledge Q&A, creative writing, code programming, and more. Feel free to ask me anything you need help with!
Either you didn’t test all the models, or the provider forgot to configure DeepSeek V4 Pro.
ask opencode to do it.
This is a good find, thanks for letting us know. Just to clarify you are referring to hcnsec API endpoint not agent router correct? Also I see that there are a few models like the Qwen models that do in fact look official. Can you confirm the Qwen models are legit? Thanks
This means the Claude Code session’s context capacity is full.
The screen shows:
-
Total capacity: 200,000 tokens
-
Context currently used: 182,100 tokens
-
Messages: 165,000 tokens
-
Free space: 0
-
Claude is automatically compacting the conversation, but the context fills up again within a few messages. This is called “autocompact thrashing.”
The problem is not your computer or your code. The problem is that the current Claude session has become too large.
What to do now
Safest method
First, click Rewind and return to the point just before Claude read a large file or generated an excessively long tool output.
Then send Claude this prompt:
Create a concise SESSION_HANDOFF.md file in the project root.

Include only:
1. The project objective
2. Work completed
3. Files created or modified
4. Important architectural and technical decisions
5. Current errors or unfinished items
6. Exact next development steps
7. Commands required to run and test the project

Do not read any large files and do not produce a long response.
Write the information directly into SESSION_HANDOFF.md.
After the file has been created, enter:
/clear
Then, in the new clean session, continue with:
Read CLAUDE.md and SESSION_HANDOFF.md first.

Then run:
- git status
- git diff --stat

Do not read the entire repository.
Continue only from the next unfinished task stated in SESSION_HANDOFF.md.
Important
The /clear command:
-
Does not delete your project files.
-
Does not delete the code changes Claude has made.
-
Only clears the conversation context.
-
Claude will not remember the previous conversation, which is why
SESSION_HANDOFF.mdis necessary.
At this stage, I do not recommend using Compact again. The message on the screen clearly indicates that automatic compaction has entered a loop. The correct solution is:
Rewind → create the handoff file → run /clear.
Its set up with opencode but models are stuck at thinking and dont respond
hey guys, has anyone noticed that all the qwen models are gone from the hcnsec api?>
hey, has anyone got agent router to work with hermes agent, I cant get it to work…Appreciate the help! thanks guys
Thanks for this - What is the Base API URL you are using for seekai to run in Hermes agents? TY
Where are the credit show? I log in with github, i not see
click on personal profile , then wallet
https://seekai.cc with Anthropic format
Thanks but it’s not $4,000 usd. It’s CNY. Still good but not as big as it seems.
Thanks! Worked for me
The 8000$ link worked with 6 accounts only. i am trying to do more. is that alright? @oberold
which has longer duration? the 8k or the 4k credit?
resource exhausted after a few conversations. doesn’t worth the hassle.
Has anyone got Agentrouter to work with Hermes agent ? Keeps failing for me… TY
I found another site you guys might like.
Link for Another Site : Tabitoken to get Opus 5 and other anthropic models and 120USD Credits
 !