 ─ ✕ ─ ─ ─


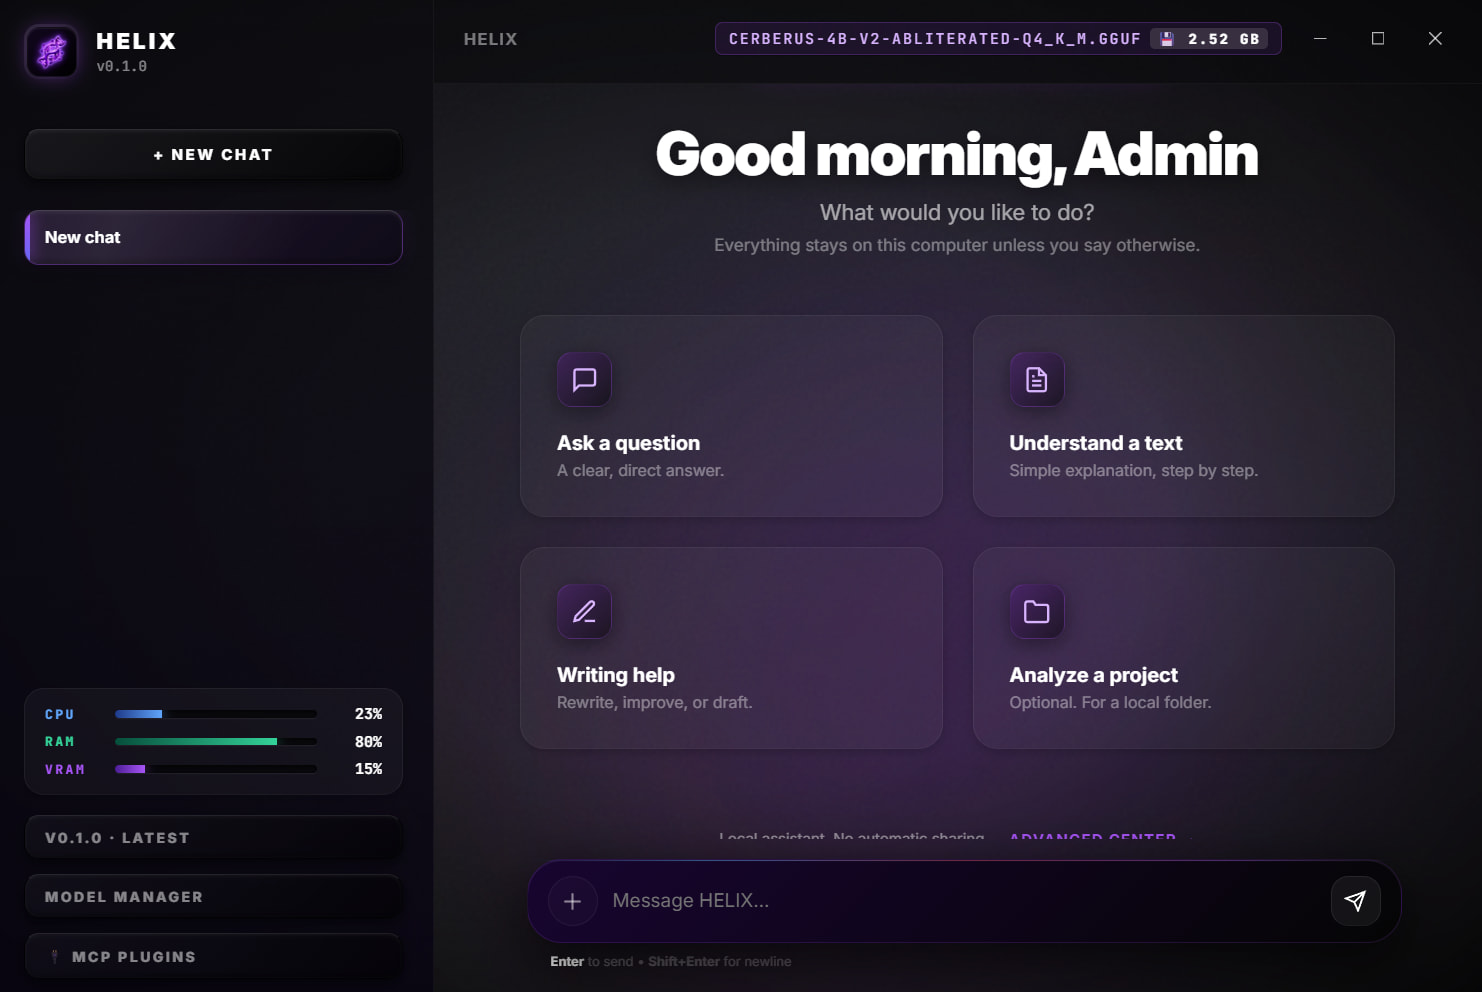
HELIX turns your own PC into a private ChatGPT — install it, pull any open model straight off HuggingFace from inside the app, and chat 100% offline. No account, no API key, no subscription, nothing ever leaves your machine. Built in Rust + Tauri, source on GitHub.
The LM Studio everyone runs is a closed binary. HELIX is the one you can open — read the source, run it on any GPU (Vulkan, not just NVIDIA), with agent plugins built in.
 Grab it — Windows
| file | size | |
|---|---|---|
| HELIX-Setup.exe | 11 MB | one-click installer |
| HELIX .msi | 18 MB | enterprise/silent install |
| verify | — | SHA256SUMS.txt on the release |
 Source + releases → github.com/tjcrims0nx/Helix
 First chat in 3 clicks (zero skill)
- Install → open HELIX
- Search a model (try
Qwen2.5-7BorLlama-3.2-3B) → one-click download (8-stream, auto-resumes) - Type. Done — running on your GPU, fully offline.
 The tour
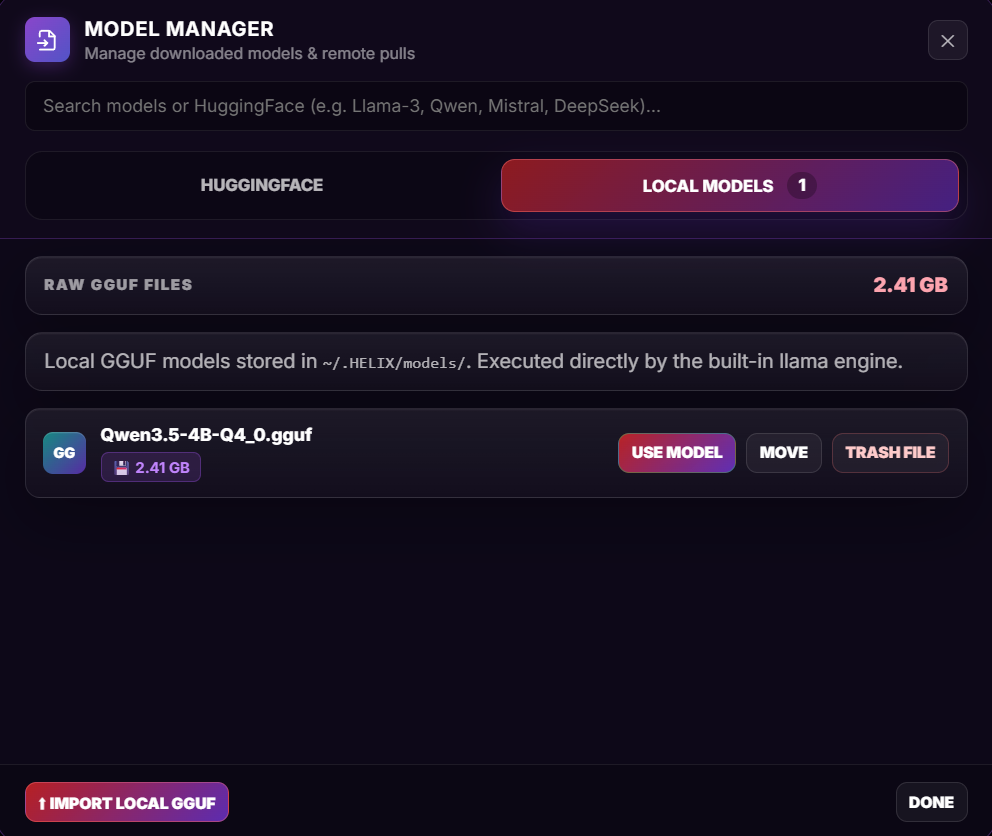
↳ Model Manager — search HuggingFace, parallel chunked pulls, live VRAM + disk analytics
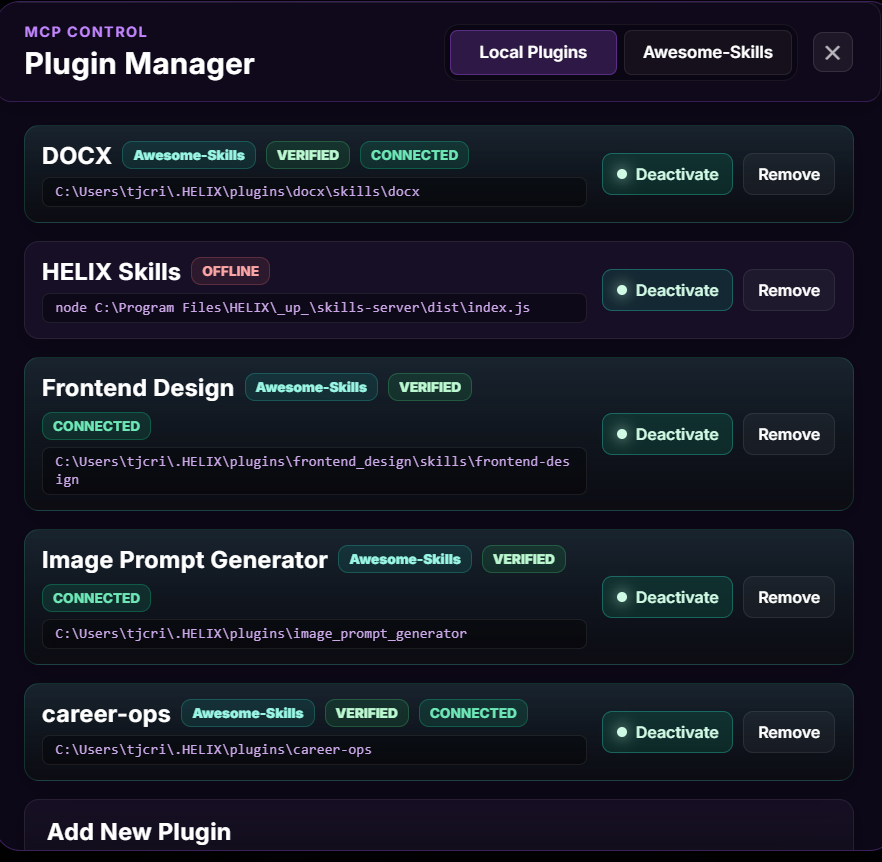
↳ MCP Plugin Manager — hand your local model real tools: files, web APIs, agent skills
🔵 Under the hood — for the tinkerers
 Vulkan + FlashAttention llama-server (
-fa auto, ~3× prompt speed) — runs on Intel Arc / AMD, not CUDA-locked MCP plugins (stdio + SSE) via in-chat
/mcp list · enable · disable · open→ wire up filesystem / web / agent tools with an auto tool-call + reasoning-trace loop Custom
.ggufimport · live model switching · real-time CPU/RAM/VRAM monitor Build from source — Tauri 2 (Rust) · Vue 3 + Vite · engine = llama.cpp
🍖 Feed it models — where the good GGUFs live
- HuggingFace · GGUF trending — the firehose of open models
- bartowski — cleanest quants of nearly every new model, days after release
 quant rule of thumb:
Q4_K_Mis the sweet spot; rough VRAM ≈ (params-B × 0.7) GB → an 8B model fits in ~6 GB
 HELIX vs the usual
| source | GPU support | agent tools | |
|---|---|---|---|
| LM Studio |  closed binary |
CUDA / Metal | MCP (recent) |
| Ollama | terminal-first | CUDA / Metal | via 3rd-party UIs |
| HELIX |  open on GitHub |
Vulkan — any GPU | built-in /mcp |
Cloud AI rents you a seat and reads the room. This one you own — on your metal, behind your door.
 !