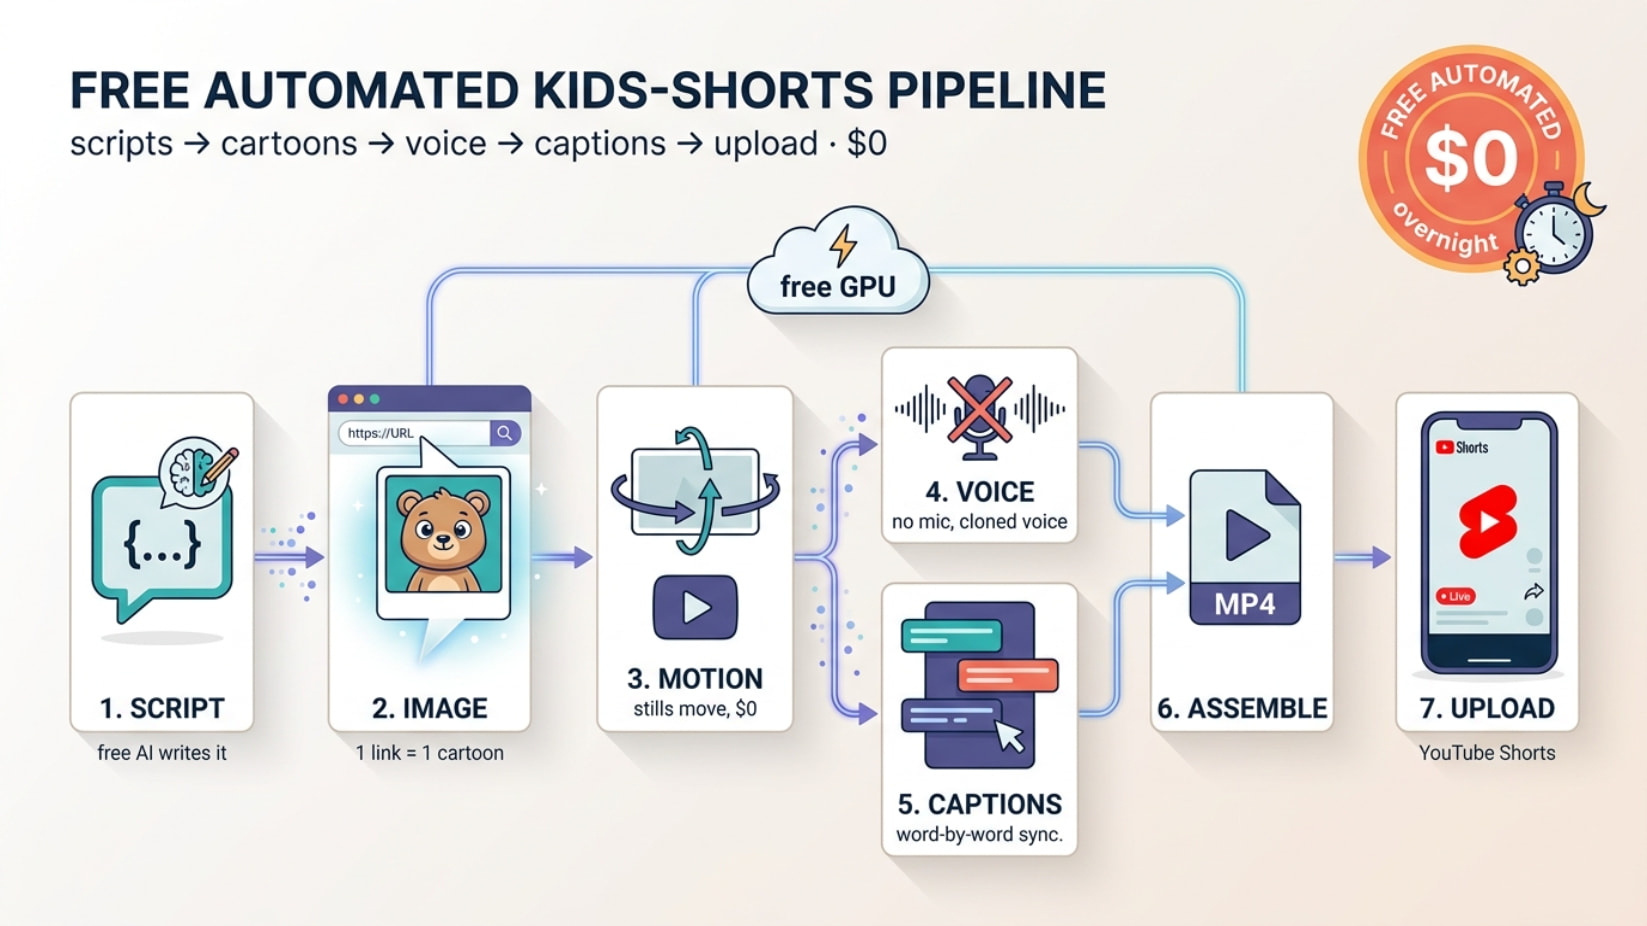
Two holes in your flow were cartoon frames + a human voice. Below is the whole machine — every stage, every free tool, the rare ones nobody posts. Brains on free API tiers, media on your CPU, heavy lifting on free cloud GPU. $0 forever.
 the brain — free scripts at volume
The script is the channel. These write hooks + narration for free:
- Groq — no card. Llama 3.1 8B = 14,400 requests/day, sub-second. OpenAI-compatible endpoint, drop-in.
- OpenRouter — add
:free to a model name → 28+ free models (DeepSeek R1, Llama 3.3 70B). 50/day free; a one-time $10 top-up (never expires) → 1,000/day.
- Puter.js — keyless, no backend.
puter.ai.chat() in browser JS hits GPT/Claude/Gemini free. Rare: genuinely no key.
- Pollinations text — keyless GET, returns plain text,
seed for repeatable output.
- Ollama — local Llama/Qwen/Gemma, fully offline, zero limits. A 3B model runs on weak hardware.
Script prompt that works → force JSON out: hook (first 2s, a question), beats (5–8 scenes), narration (one simple sentence each), visual_prompt (with a fixed character block prepended every time = consistency), caption_keywords, cta.
 cartoons from a link — no key, no signup
Pollinations.ai → hit a URL, get a JPG. No account, no API key.
import requests, urllib.parse
p = urllib.parse.quote("cute cartoon bear, flat design, bright, kids, simple")
url = f"https://image.pollinations.ai/prompt/{p}?width=720&height=1280&nologo=true"
open("scene.jpg","wb").write(requests.get(url, timeout=120).content)
720x1280 = vertical Short baked in. Ugly frame? Call it again, it’s free. Swap engines with ?model= → flux nanobanana seedream qwen-image gptimage.
Backups + keyless alts:
Same character every scene (the hard part):
 Seed lock — fix the seed across a batch for stable style.
 IP-Adapter FaceID (in ComfyUI) weight 0.7–0.85 = face lock; + a character LoRA for outfit.
 No-LoRA trick: generate one 360° orbit clip with LTX-Video, extract frames — the video model forces consistency for free.
 rembg — cut character off background. Model
isnet-anime is built for cartoons. CPU ~0.5s/img. Real-ESRGAN (anime model) — crisp 1080×1920 from cheap low-res.
 make stills move — for free, on CPU
Faceless motion = the FFmpeg Ken Burns pan/zoom. No compute cost:
ffmpeg -i scene.jpg -vf "scale=8000:-1,zoompan=z='min(zoom+0.0015,1.5)':d=125:\
x='iw/2-(iw/zoom/2)':y='ih/2-(ih/zoom/2)':s=1080x1920" -t 5 motion.mp4
 Parallax: rembg the character out, zoompan foreground + background at different speeds, overlay → cheap 2.5D depth.
 LTX-Video — fast image→video, runs on 12GB VRAM (or free Kaggle T4). Real motion from a still.
 AnimateDiff-Lightning — 8GB VRAM, keeps your style, adds looping motion in few steps.
Talking-character cartoons (lip-sync, free, needs GPU → use Kaggle):
 SadTalker — 1 image + audio → talking head w/ head motion.
 Wav2Lip — most accurate mouth sync, zero-shot.
 MuseTalk — newer, sharper, real-time on GPU.
 the voice MS left sitting in plain sight
Edge TTS = Microsoft neural voices, free, no key. pip install edge-tts.
The cheat: en-US-AnaNeural is Microsoft-tagged “Cartoon, Cute.” A kid voice, built-in, free.
import edge_tts, asyncio
asyncio.run(edge_tts.Communicate("Hello friends! Meet a sleepy bear.",
    voice="en-US-AnaNeural").save("voice.mp3"))
Swap voice → new presenter: JennyNeural AriaNeural AvaNeural GuyNeural en-GB-SoniaNeural (400+).
The rare upgrade — clone any voice, add emotion, free:
 Chatterbox (MIT) — clone a voice from ~7s, emotion control,
[laugh] tags, 23 languages. Resemble’s blind test: 63.75% preferred it over ElevenLabs. Commercial-safe. Kokoro TTS — 82M, CPU, 4GB RAM, offline. Voices:
af_bella af_sarah am_michael bf_emma bm_george. Piper (repo moved here — old one archived) — runs on a Raspberry Pi, <1GB, instant offline narration.
 MeloTTS (MIT) — real-time on CPU, multi-accent.
 Coqui — local,
tts_models/en/vctk/vits. gTTS — dead-simple drafts. Fish Audio — premium cloud, free ~8k credits/mo.
 Monetizing? License check: XTTS-v2, F5-TTS, Bark, open Fish Speech = non-commercial. Safe for money: Chatterbox · Kokoro · Piper · MeloTTS · Edge TTS.
 the retention multiplier nobody mentions: captions
Word-by-word animated captions = the single biggest Shorts watch-time lever. All free:
- ai-video-captions (MIT) — self-hosted Submagic clone: Hormozi / MrBeast / Karaoke styles, word-level, 100+ languages. Docker, CPU-viable.
- faster-whisper — 4× faster transcription, int8 = CPU-efficient, word-level timestamps. Best low-end pick.
 WhisperX — sub-100ms forced alignment = true karaoke sync.
 Captacity (MIT) — one-command Hormozi word-highlight burner.
pip install captacity.
 sound that doesn’t get you struck
 Pixabay API — free key, 120k+ royalty-free music + SFX, no attribution, commercial-safe.
 Freesound API — huge SFX (filter by license).
 YouTube Audio Library (in Studio) — safest for monetization.
- Auto-duck music under narration (FFmpeg sidechain — music dips when voice talks):
ffmpeg -i music.mp3 -i voice.wav -filter_complex \
"[0:a][1:a]sidechaincompress=threshold=0.03:ratio=8:attack=20:release=300[a]" \
-map "[a]" mixed.wav
 the glue: image + voice → mp4
FFmpeg welds them. -shortest auto-matches video length to the voice.
import subprocess
subprocess.run(["ffmpeg","-y","-loop","1","-i","scene.jpg","-i","voice.mp3",
    "-c:v","libx264","-tune","stillimage","-c:a","aac","-pix_fmt","yuv420p",
    "-shortest","short.mp4"])
More assembly: MoviePy (Python editing), auto-editor (auto-cuts silence → tighter retention), Pexels API (free keyword B-roll from your caption_keywords). Vertical-fit landscape = blurred-bg fill + centered overlay, no black bars.
 steal this — full pipeline, one run
import requests, urllib.parse, asyncio, edge_tts, subprocess

def img(prompt, f):
    p = urllib.parse.quote(prompt)
    u = f"https://image.pollinations.ai/prompt/{p}?width=720&height=1280&nologo=true"
    open(f,"wb").write(requests.get(u, timeout=120).content)

async def vo(text, f):
    await edge_tts.Communicate(text, voice="en-US-AnaNeural").save(f)

def vid(i, a, o):
    subprocess.run(["ffmpeg","-y","-loop","1","-i",i,"-i",a,"-c:v","libx264",
        "-tune","stillimage","-c:a","aac","-pix_fmt","yuv420p","-shortest",o])

img("cute cartoon bear, flat, bright, kids", "scene.jpg")
asyncio.run(vo("Hello friends! Meet a sleepy bear.", "voice.mp3"))
vid("scene.jpg", "voice.mp3", "short.mp4")
multi-scene version (slideshow Short)
Each scene = its own clip → stitch. Picture stays up exactly as long as its line, so audio never drifts.
import requests, urllib.parse, asyncio, edge_tts, subprocess

scenes = [
    {"img":"cartoon student in Germany, flat, kids", "line":"Germany has free university."},
    {"img":"cartoon kid with laptop, shield, cyber, kids", "line":"Cybersecurity is the fastest-growing job."},
    {"img":"cartoon graduation, confetti, kids", "line":"Your journey starts with one application."},
]
def img(prompt,f):
    p=urllib.parse.quote(prompt)
    u=f"https://image.pollinations.ai/prompt/{p}?width=720&height=1280&nologo=true"
    open(f,"wb").write(requests.get(u,timeout=120).content)
async def vo(t,f): await edge_tts.Communicate(t,voice="en-US-AnaNeural").save(f)
def clip(i,a,o):
    subprocess.run(["ffmpeg","-y","-loop","1","-i",i,"-i",a,"-c:v","libx264","-tune",
        "stillimage","-c:a","aac","-pix_fmt","yuv420p","-vf","scale=720:1280","-shortest",o])

clips=[]
for n,s in enumerate(scenes):
    img(s["img"],f"i{n}.jpg"); asyncio.run(vo(s["line"],f"a{n}.mp3"))
    clip(f"i{n}.jpg",f"a{n}.mp3",f"c{n}.mp4"); clips.append(f"c{n}.mp4")
open("list.txt","w").write("".join(f"file '{c}'\n" for c in clips))
subprocess.run(["ffmpeg","-y","-f","concat","-safe","0","-i","list.txt","-c","copy","final.mp4"])
pip install requests edge-tts kokoro-onnx soundfile faster-whisper captacity
# FFmpeg → Win: winget install ffmpeg | Linux: apt install ffmpeg | Mac: brew install ffmpeg
 post it on autopilot — free
YouTube Data API v3 = free uploads. videos.insert sets title/desc/tags + status.publishAt for native scheduling. Must set selfDeclaredMadeForKids (COPPA). Shorts = 9:16, <60s, #Shorts in title.
- Quota math: one upload = 1,600 units, daily cap 10,000 → ~6 uploads/day/project (resets midnight PT). Need more → spin up extra Google Cloud projects (free).
 n8n (free self-hosted) — visual glue: idea → script → TTS → images → FFmpeg → upload, all wired, no custom code.
 Bulk thumbnails: Pillow/PIL text-overlay on a frame. (Note: custom thumbnails don’t apply to Shorts.)
 free ideas + free GPU farm
- Trends free: YouTube search autocomplete (ranked by real volume) + Google Trends + vidIQ/TubeBuddy free keyword tools.
 Kaggle Notebooks — free dual-T4 GPU, ~30 hrs/week, no decay, 32GB RAM. Run ComfyUI/LTX-Video/lip-sync your weak PC can’t. Colab free T4 = backup.
 HF Spaces + ZeroGPU — free A100 bursts, no install.
 Stack tiers as lanes: Groq (speed) → OpenRouter free → Pollinations/Puter. Cache the system prompt on Groq — cached tokens don’t count against limits.
 the whole kit
| Stage |
Free pick |
Type |
Weak PC |
| Script |
Groq / OpenRouter / Ollama |
cloud / local |
 |
| Image |
Pollinations / Puter / SD |
cloud / local |
/ GPU |
| Consistency |
IP-Adapter + seed lock |
local |
GPU |
| Motion |
FFmpeg zoompan / LTX-Video |
local / cloud |
/ |
| Lip-sync |
Wav2Lip / SadTalker |
cloud GPU |
Kaggle |
| Voice |
Edge TTS / Chatterbox / Piper |
cloud / local |
|
| Captions |
faster-whisper + ai-video-captions |
local |
|
| Music |
Pixabay API / YT Audio Library |
cloud |
|
| Assembly |
FFmpeg / MoviePy |
local |
|
| Upload |
YouTube Data API v3 |
cloud |
|
| GPU farm |
Kaggle dual-T4 |
cloud |
free |
Weak-PC lane: Pollinations + Edge TTS + faster-whisper + FFmpeg (CPU barely wakes).
Offline lane: SD + Kokoro/Piper + whisper.cpp.
Quality lane: Kaggle GPU + Chatterbox + IP-Adapter + ai-video-captions.
where this actually prints
 Queue overnight → wake to 20 Shorts done while you slept.
- No mic, no face — clone one voice once (Chatterbox), narrate forever.
 No GPU? Cloud tools never touch your CPU; offload the rest to free Kaggle T4.
 Run 5 channels at once — same code, swap prompt + voice, $0 extra.
 Karaoke captions auto-burned = the retention bump paid tools charge $30/mo for.
 Test a niche cheap — pump 10 videos, kill it if it flops, nothing burned.
A studio that fits in one script and runs on a machine you’d throw away.

 Offline:


 No-signup web:
 !