I have a NLP task for which Gemma4 31B is best suited. Using it with Cerebras Cloud works but hits daily limit very quickly and I dont have hardware to deploy locally. Google AI Studio also give up on limits. How can use this model only?
ollama. Its free
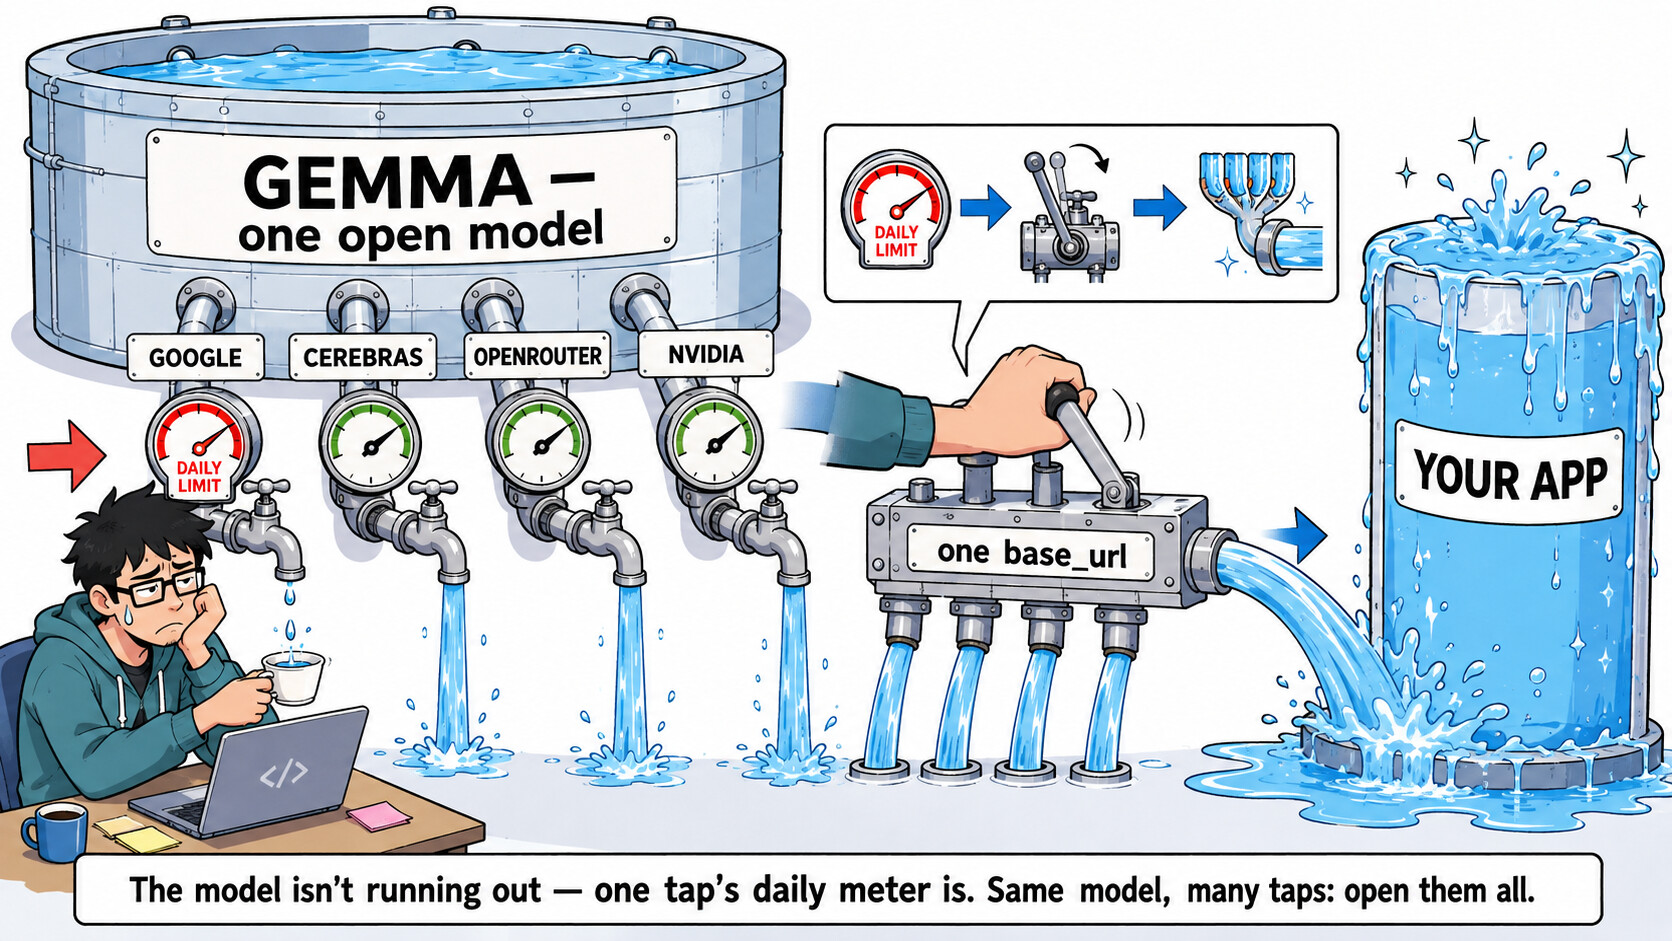
Gemma is open-weights — Cerebras and Google don’t own it, they’re just two hosts among many. That “daily limit” is one provider’s throttle, not the model’s. The same Gemma runs on a dozen clouds behind the standard chat API, so you hop hosts by changing one base_url — and stacked free tiers add up to one big daily quota. (Reply above said Ollama — that’s local, which you can’t do; this is all cloud, no GPU.)
 The one-line swap — same code, any host
from openai import OpenAI
c = OpenAI(base_url="https://openrouter.ai/api/v1", api_key="YOUR_KEY")
c.chat.completions.create(
    model="google/gemma-3-27b-it:free",
    messages=[{"role": "user", "content": "..."}])
↳ change base_url + api_key + model → you’re on a different host. Nothing else in your code moves.
 Where Gemma runs free (no card) — ranked by daily headroom
| Host | Free / day | model |
base_url |
|---|---|---|---|
Google AI Studio  not in EU/UK |
~14,400 req | gemma-3-27b-it |
generativelanguage.googleapis.com/v1beta/openai/ |
| card required now |
$5 credit, then pay-per-token | gemma-4-31b * |
api.cerebras.ai/v1 |
OpenRouter  also the rotator |
50 → ~1k req † | google/gemma-3-27b-it:free |
openrouter.ai/api/v1 |
| NVIDIA NIM | ~40 RPM · no hard cap | google/gemma-3-27b-it |
integrate.api.nvidia.com/v1 |
* preview slot — verify the live id first · † 50/day jumps to ~1,000/day after a one-time $10 credit (the :free calls don’t spend it)
You’re already on Cerebras + Google — so just add OpenRouter + NVIDIA, then fuse all four into one quota 
Make N free tiers act as ONE big quota
- OpenRouter — one key already fans out across every upstream serving free Gemma, with built-in failover. Zero setup — make it your default tap. → https://openrouter.ai/google/gemma-3-27b-it:free
- LiteLLM proxy (self-host) — the real stacker: list
model_name: gemmaonce per provider (your Google / Cerebras / OpenRouter / NVIDIA keys), add afallbacksline → it round-robins and skips any key the moment it429s. Your app points at one localhttp://localhost:4000/v1. → https://docs.litellm.ai/docs/proxy/reliability - LLM-API-Key-Proxy — pool many keys per provider (e.g. 3 free Google keys) with auto-cooldown + failover. → https://github.com/Mirrowel/LLM-API-Key-Proxy
⚠️ Gotchas that bite a naive swap (read once)
- Cerebras killed its no-card free tier on Aug 17, 2026 — existing accounts got a migration email; it’s now add-a-card-for-$5-credit, then pay per token. Google AI Studio, OpenRouter, and NVIDIA below are still genuinely free, no card.
- Your “Gemma 4 31B”: Cerebras / NVIDIA / OpenRouter carry the newer v4, but preview/
:freeslots rotate — verify the exact id live (filter https://openrouter.ai/models by $0). Everywhere else,gemma-3-27b-itis the guaranteed drop-in — same request body. - IDs differ by host:
google/prefix on OpenRouter/NVIDIA (OpenRouter adds:free) vs bare id on Google/Cerebras. Onlybase_url+key+modelchange. - Dead ends — don’t waste time: Groq, Together, and GitHub Models have no Gemma in their catalogs anymore.
- Google’s
/openai/path sometimes serves Gemini only — if agemma-*id 404s, use Google’s nativegenaiSDK, or just reach Google’s Gemma quota through OpenRouter. - Overflow tap: after the standing-free hosts
429, DeepInfra ($5) / Nebius (~$5–10) hand out one-time credit (no card), then pennies/1M tokens.
The model was never the wall — the meter was. Spread it across meters and the wall’s gone.
Hello Friend, You may also want to check out > https://omniroute.online/
Let me know if this works for you!
Cheers
Thank you all, solved 
9router also works fine: https://9router.com
what do you usually use agent on this kind of setup for Gemma4 31b?
hermes or openclaw?
Thanks to all in community for helping. Cerebras will move to paid tier on 14th Aug. I got the mail from them. Google AI Studio is working and probably the best with a very generous limit.
I saw @Thorgal tell about 9router. I have set it up. That helps as well.
Thanks again 
@niggaplsss I dont use agent (I don’t know how  to use). I have prose, dense text which I need converted to bullet points. So i copy-paste chunks in playgorund using Gemma4 31B in Google AI Studio and ask it. I have give it a system prompt so every time i give it text, gemma returns in bullet points.
@Vishal_Jain2 — checked independently, matches your email exactly: Cerebras killed the no-card free tier on Aug 17, 2026. Existing accounts move to add-a-card-for-$5-credit, then pay per token. Not a scam mail, just reality — corrected the table above  . Good that Google AI Studio’s holding a generous limit and 9router’s covering the gap.
On 9router specifically — worth a 2-minute check since you’ve already got it running. It shipped a critical bug, CVE-2026-49352: a hardcoded fallback JWT secret that lets anyone on the internet forge a login cookie and pull every API key sitting in its dashboard, if JWT_SECRET was never set. Fixed in v0.4.45+.
npm list -g 9router
Below 0.4.45 → npm update -g 9router. Or just set a real JWT_SECRET env var yourself — either one kills the bug. Two minutes, worth doing before more keys sit behind it.
@gman20’s omniroute.online is the same family — literally a fork of 9router, way more providers. Independent reviews flag it harder though: API keys stored unencrypted by default, guardrails that fail open on error, and TLS-fingerprint spoofing built in specifically to dodge provider anti-abuse detection. Fine for solo tinkering behind a throwaway key, not for anything you’d mind losing.
@niggaplsss — Hermes and OpenClaw aren’t competing for Gemma specifically. Both are self-hosted personal-agent frameworks that happen to accept any OpenAI-compatible endpoint, so either one just points straight at the setup above .
- Hermes Agent (Nous Research) — Python, CLI-first, self-improving skill library, 300+ models via its own Portal or a custom endpoint.
- OpenClaw — Node/Docker, web dashboard, 30+ plugins, same custom-endpoint support.
Pick by workflow — CLI + skills-that-learn vs dashboard + plugins — not by Gemma support. Both run it fine through OpenRouter/NVIDIA.
 !